A business approached us after its AI agent started struggling with real-world tasks despite performing well during demos. The agent was connected to live business systems, but vague instructions and insufficient testing led to unexpected tool calls and incomplete workflows. The problem wasn't the model itself; it was how the agent had been instructed and deployed.
Across 150+ client engagements, BuildNexTech has seen how effective prompt engineering for agentic AI can turn simple instructions into reliable business actions. This requires clearly defined roles, precise tool instructions, structured outputs, and appropriate guardrails. This guide explains how to design, validate, and govern AI agents before they interact with live business systems.
Why Agentic AI Needs a Different Kind of Prompting
A chatbot prompt shapes one visible reply. An agent prompt steers a dozen steps nobody watches, so an early ambiguity compounds silently into:
- A wrong tool call.
- A retry loop.
- A half-finished write.
Gartner predicts that 40% of enterprise applications will include task-specific AI agents by the end of 2026, up from under 5% in 2025. Existing guidance leaves a gap:
- Developer tutorials stop at cognitive architectures such as ReAct and Tree of Thoughts.
- Vendor guides stop at governance.
- Agentic AI frameworks such as LangChain supply the plumbing, not the instructions.
Although context engineering is important, this guide keeps focused on the question. In roughly two weeks, one constrained workflow can have a regulated prompt.
What Is Agentic AI and Generative AI?
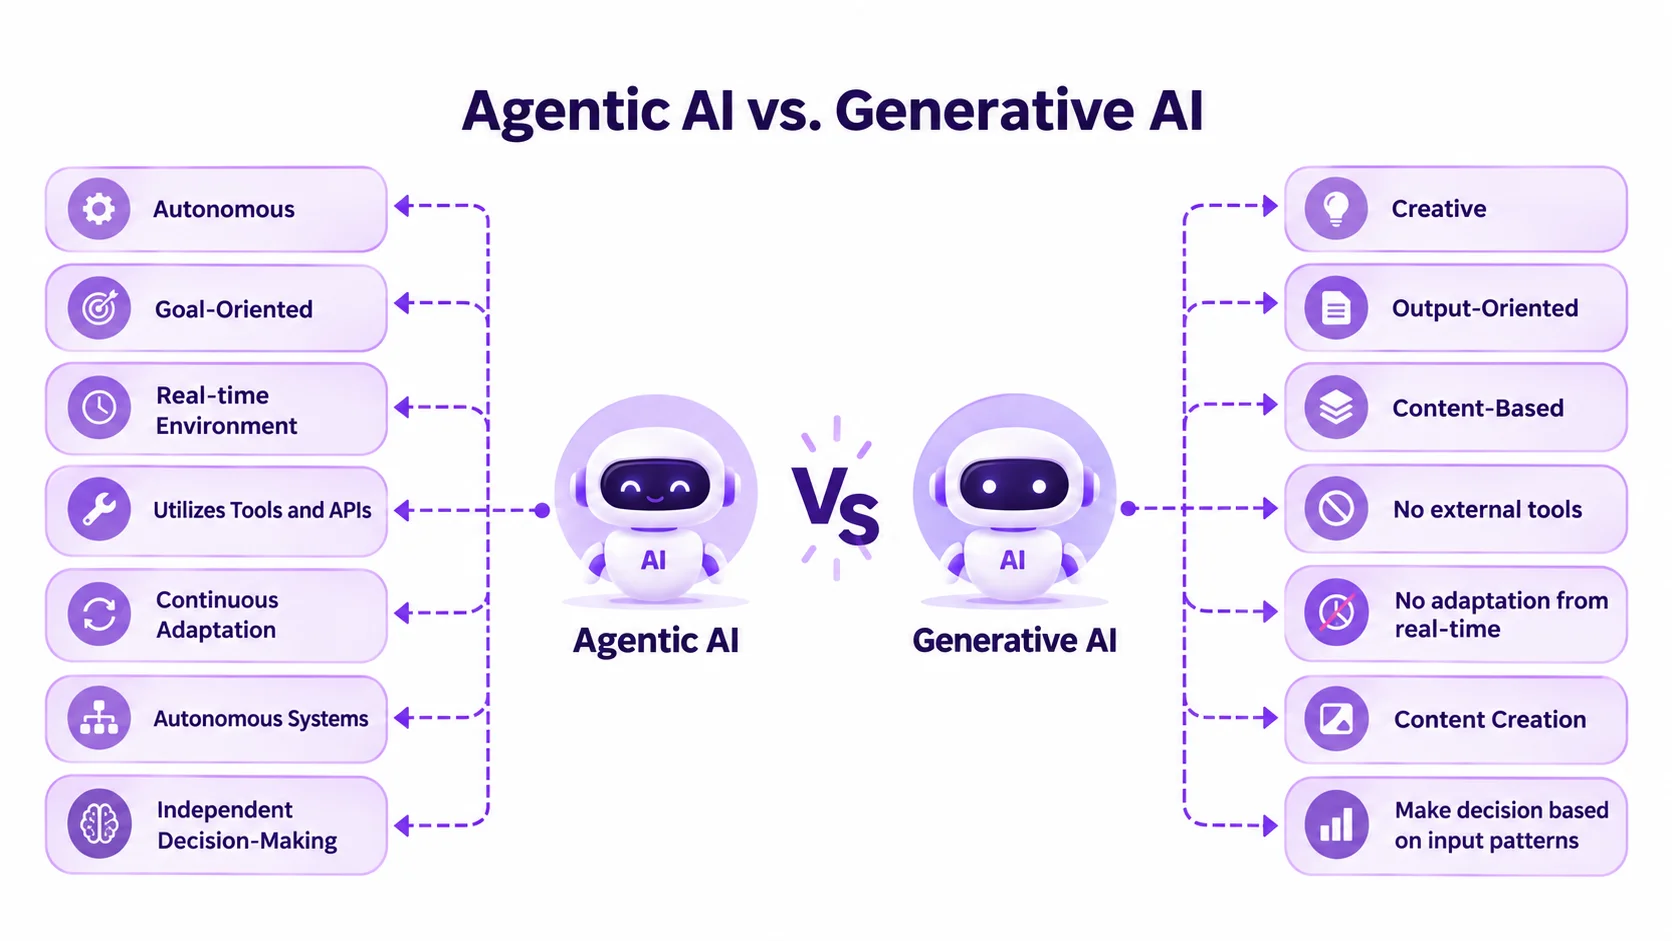
Generative AI creates content such as text, code or images in response to a prompt. Agentic AI has a goal: It is making plans, calling tools and acting on business systems with minimal supervision.
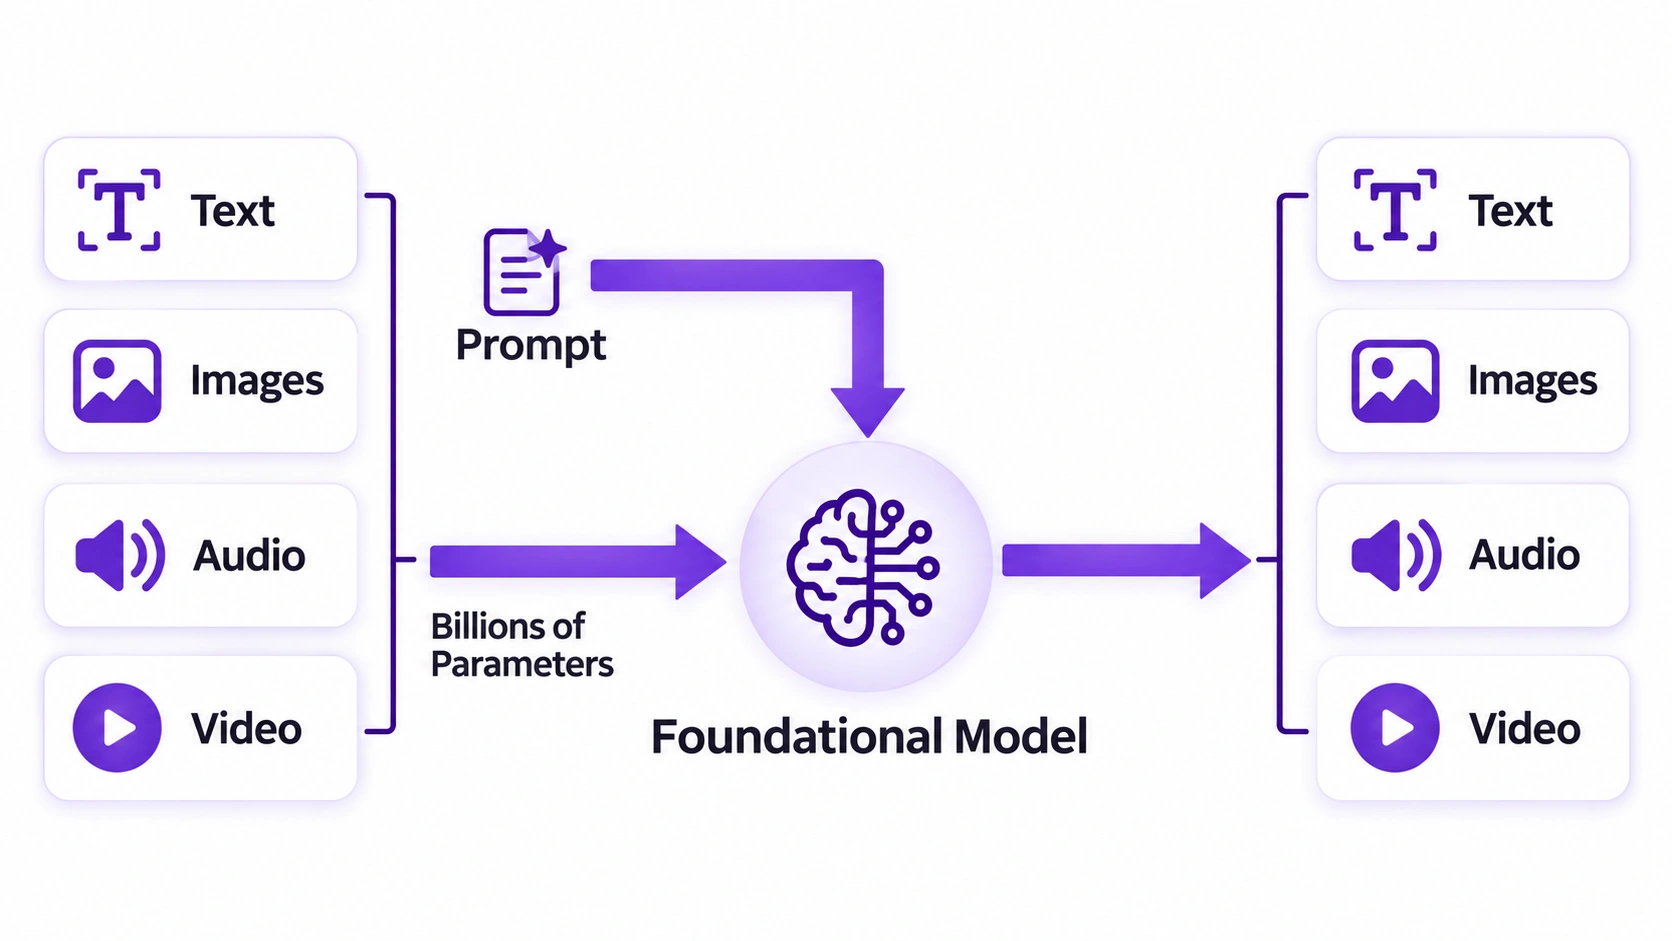
- Generative AI: One output, person reviewed.
- Agentic AI: Numerous actions, each influenced by the preceding outcome.
Most agents are based on a generative model below. All of the surrounding things change: Tools, memory, permissions.
Agentic AI vs Generative AI: Where Prompts Change
The same model behaves differently when a system, not a person, reads its output. Architecture is covered in our guide to developing sophisticated agentic AI systems with Claude and LangChain.
Failure visibility is the row most teams underrate. A chatbot's wrong answer is on screen within a second, while an agent's wrong write sits in a database until month-end reconciliation.
What Prompt Engineering Means for AI Agents
Goals, constraints, context and decision rules ultimately determine what a model chooses to do over many steps, and it's not what is said in the words. What does LLM mean? Acronyms for "large language model. In a nutshell, what is LLM in AI? A reasoning engine that chooses a next action, based upon a prompt as its workflow specification. The two words that are jumbled are:
- User prompts are what people type into the interface.
- The LLM prompt is everything the model receives: System instructions, tool definitions, memory and the user prompt together.
The person who owns the prompt (AI professional, machine learning engineer or product owner) should consider it a specification. You'll not be able to change your agent with better phrasing. Once the model can call an API, a prompt that is effective in a chat window begins to have its issues and will generate a wrong transaction when using a vague sentence.
The Anatomy of an Agent Prompt That Triggers Business Actions
Agent design starts with the layer between a business instruction and a system call. Role, tools and output structure decide whether it holds.
Defining the Agent's Role, Goal, and Scope
Aim for the right altitude: Specific enough to constrain, flexible enough to handle variation. Four things are covered by a robust system prompt:
- Behavior & Personality: succinct tone and decision-making approach.
- Rules and Constraints: The agent is not allowed to reach certain conclusions.
- Memory management: What carries between steps and what gets dropped.
- Reasoning cues: Tree of Thoughts to compare options, multi-hop reasoning for questions needing several lookups.
WEAK
You're an extra helpful billing assistant. Resolve disputes quickly.
STRONG
Function: Agent to resolve billing issues.
Goal: Determine the nature of the conflict and develop a solution for discussion.
Tasks: Reads invoices and tickets; writes refunds up to £200.
Must NOT: Approve Refunds, Edit Payment Records, or Assume
Information beyond the content of the ticket.
If in doubt: return "needs_clarification".
The strong version cannot approve anything and must escalate rather than guess. That one boundary would have prevented the £4,200 refund.
Writing Tool Definitions for Function Calling
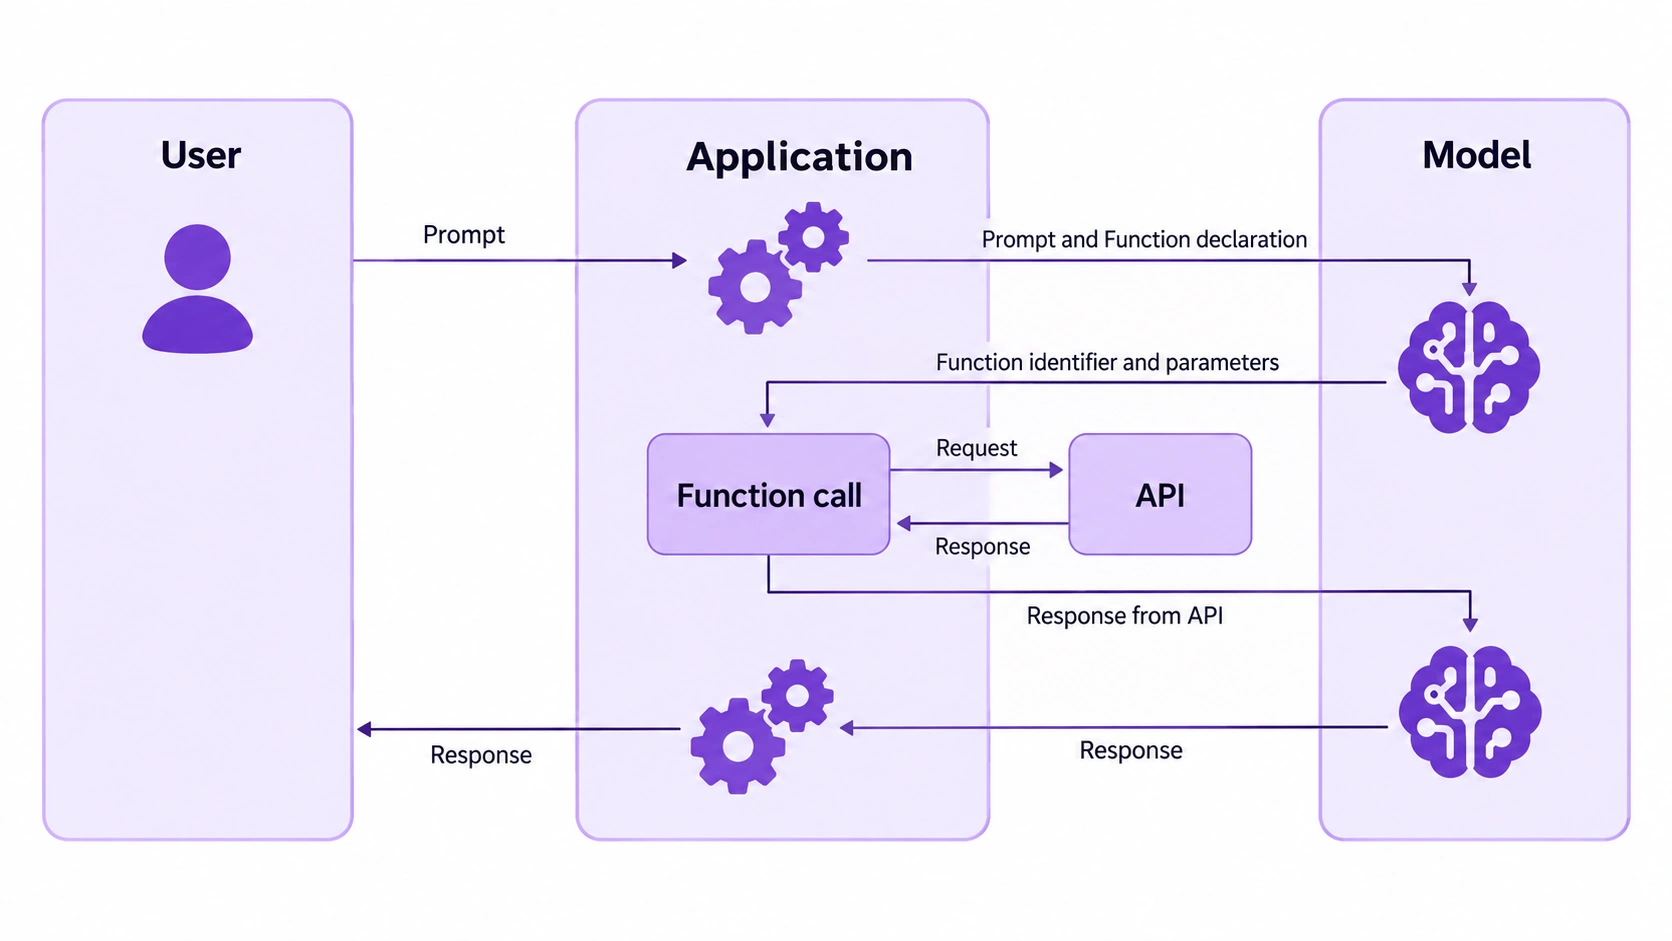
Function calling lets the model request a named tool with structured arguments. Your description is the only guidance it gets on tool use.
- Vague: "Updates records." It does not communicate anything to the agent.
- Precise: "Updates a CRM contact field after the customer confirms that the data has been updated; do not use it for billing data.
- One tool, one job. Agents are not inclined to continue to use external tools when they overlap. Agents don't want to keep using external tools if they overlap.
- When choosing a function-based name, I prefer to select a name that looks like a sentence, like create_ticket or update_crm_record.
Anthropic and OpenAI both document this pattern, and good tool integration depends on it.
Structuring Outputs So Systems Can Act on Them
Most top-ranking guides stop when the model replies. The real work starts there.
{
  "action": "draft_refund",
  "ticket_id": "T-48213",
  "amount_gbp": 180.00,
  "reason_code": "duplicate_charge",
  "confidence": "high",
  "needs_clarification": false
}
The agent's reply is only a proposal. Before any action is executed, a downstream validation service checks the output against a predefined schema to ensure it meets the system's requirements and safety rules:
- Required fields are present: Confirms that essential details, such as the ticket ID, amount, and reason, are included.
- The amount sits within bounds: Ensures the proposed amount stays within predefined limits.
- The action is on an allowed list: Verifies that the requested action is permitted, such as drafting a refund rather than approving it.
- Generated SQL commands are restricted: Checks that database queries access only authorised tables and perform permitted operations before execution.
If any check fails, the system should reject the output or send it for human review rather than execute an unsafe or incomplete action.
When input is ambiguous, the agent returns needs_clarification and a person handles the case. Setup time: Roughly two to three days for one workflow's schema and validator.
Our Take: Write the output schema before the system prompt. Teams that start with prose retrofit validation after the first bad action, while teams that start with the schema find the prompt nearly writes itself.
Most teams reach this point about six weeks in, when a wrong action first touches a live system. The fix is not a longer prompt: Instrument the agent, find the three highest-risk actions and wrap validation around them. That is how a US digital bank cut manual underwriting by 65% with our agentic AI, at a cost of days, not months.
Connecting Agent Prompts to Business Systems
Agents are best used as parts of existing workflows, rather than as replacements. The same applies to the documentation of the agent by UiPath, and the integration of Artificial Intelligence into the business is best done where each agent fits into a business process with its own owner.
When agents get multiplied, Multi-Agent Ecosystems require structure. The narrowest are the best AI agents, and three layers maintain their coordination:
- Multi-agent collaboration: Narrow agents have one job each.
- Agentic orchestration: Work is coordinated by one agent and results are passed along.
- Supervisor layers: Each output is sent to a checking agent before the next one is sent to an agent.
Mapping Instructions to AI Integration Points
Take the instruction "resolve this billing dispute." It may involve three business systems, each with a specific tool and permission to prevent unauthorised actions:
- CRM: Read-only access to retrieve customer history, account details, and previous interactions without modifying records.
- Ticketing: Permission to create tickets and add comments to document the issue and proposed resolution.
- Payments: Draft-only access to prepare a proposed payment-related action without executing it.
Failure handling should follow a clear rule: retry once if a tool call fails, then escalate to a human with the complete execution trace, including the error, tool inputs, and previous attempts. Repeated retries can reproduce the same failure, waste resources, and increase the risk of unintended actions.
Our AI integration consulting draws this map on one page before anyone writes a prompt, which keeps AI business integration auditable. Refund flows often touch a fraud service nobody listed.
Prompting for AI Workflow Automation
Write outcome-based prompts, not step-by-step procedure lists. “Prepare a resolution a reviewer can approve in one click” allows the agent to select a route for the resolution while a numbered procedure breaks when reality does not move one step forward.
Fixed steps are kept in existing workflow automation tools and workflow automation software, and are executed using deterministic rules in the workflow engine. On top of that, a judgment layer is added by AI workflow automation tools, and prompts and rules are kept short and auditable on low-code platforms. Use prompt optimisation tools: Test each version of the prompt before production with fixed test cases. The split is the same for all use cases:
- The Autonomous Coding Assistants, which open pull requests for review: Software Development.
- Customer service bots: Respond to customer inquiries, triage and draft responses, and gate refunds.
- Use Robotics & IoT to read the alerts from sensors and elevate maintenance orders.
- Document workflow automation: Read contracts and route for approval.
- Automation bot tasks such as invoice matching, an example of AI for process automation.
When designing an AI workflow, each instruction must be assigned to the right component to ensure reliable and safe execution. Some rules require consistent, predictable behaviour, while others require the agent to interpret context or involve human judgement.
Where should each rule live?
- Does the rule need to produce the same result every time? Put it in the workflow engine, where deterministic rules can execute consistently.
- Does the task require interpreting unstructured text or context? Define it in the prompt so the agent can apply judgement.
- Would a mistake have serious consequences? Add a human approval step, regardless of where the rule is implemented.
Guardrails for Safe and Governed Agent Actions
A retailer allowed its support agent to have write credentials to its payments API "just for testing". Three weeks later it was still open and nobody was able to say who had authorised what refund.
A prompt is not a security control. Prompts may be ignored, inserted or misread; enforcement is independent of them.
Setting Permission Boundaries and Human Approval Steps
Least privilege means each agent role gets only the access its task needs. Approval then scales with risk, instead of one blanket human-in-the-loop rule people learn to click through.
Thresholds and logs decide whether approvals mean anything in practice. Two details matter:
- Thresholds need an owner. Finance, not engineering, should set the £200 line, and it belongs in configuration, not prompt text.
- Every tier writes an audit log: Prompt version, tool call, validation result, approver and a request identifier such as a Cloudflare Ray ID, so a failed call traces end to end.
Applying Ethical AI Development Checks
The road to practical ethical AI development begins after the checks are mapped to named controls:
- The NIST AI Risk Management Framework provides four functions (govern, map, measure, manage) that are test cases.
- SOC 2 controls help manage and access data.
- Add bias checks, data limits and escalation rules to the prompt, and test it against defined metrics.
Regulated sectors often require controls tailored to their specific compliance and operational needs. For example, a US health system reportedly reduced administrative workload by 40% using AI virtual assistants. However, such results depend on the implementation and should be supported by documented case studies. The NIST AI Risk Management Framework provides guidance for managing AI risks through governance, measurement, and ongoing monitoring. Prompt-level checks alone are not sufficient; production agents also need independent validation, access controls, audit logs, and regular reviews.
How BuildNexTech Helps You Build Prompt-Driven AI Agents
BuildNexTech's low-code agent builder centralizes the prompts, definitions of tools, and structured outputs. That provides teams with three things:
- One versioned unit: The instruction to action path is reviewed and rolled back in a manner similar to coding.
- Enterprise grade observability: All decisions, tools calls & approvals are recorded.
- No model lock-in: Change models without having to rewrite prompts.
This put an end to the unaccountable Friday afternoon edit. Our AI consulting services and custom AI development are based on the same principle: Version everything.
There are two options teams can take: in-house or AI consulting companies like Accenture or ThoughtWorks, or a platform. Agentic AI successfully resolved 64% of IT tickets for a 400 store locations US retailer in one deployment. There are additional outcomes found in our case studies.
What a BuildNexTech Agent Implementation Looks Like
A structured implementation approach helps ensure that AI agents are integrated safely, tested thoroughly, and aligned with business goals.
- Discovery (Days 1–3): Map existing workflows, identify decision points, and define the agent’s scope and requirements.
- Integration (Days 4–7): Connect the agent to business systems, configuring one tool and its permissions at a time.
- Deployment (Week 2 onward): Launch the highest-volume workflow first, with human review and validation in place.
- Iteration and Monitoring (Ongoing): Track agent decisions, tool calls, and errors to identify improvements and refine prompts.
By the end of the rollout, your team owns the prompts, schemas, approval tiers, and audit logs. A clearly defined AI implementation strategy establishes the scope, milestones, and requirements for AI agent development from the outset.
Better phrasing will not fix your agent. The moment a model can call an API, a vague sentence becomes a wrong transaction.
Conclusion
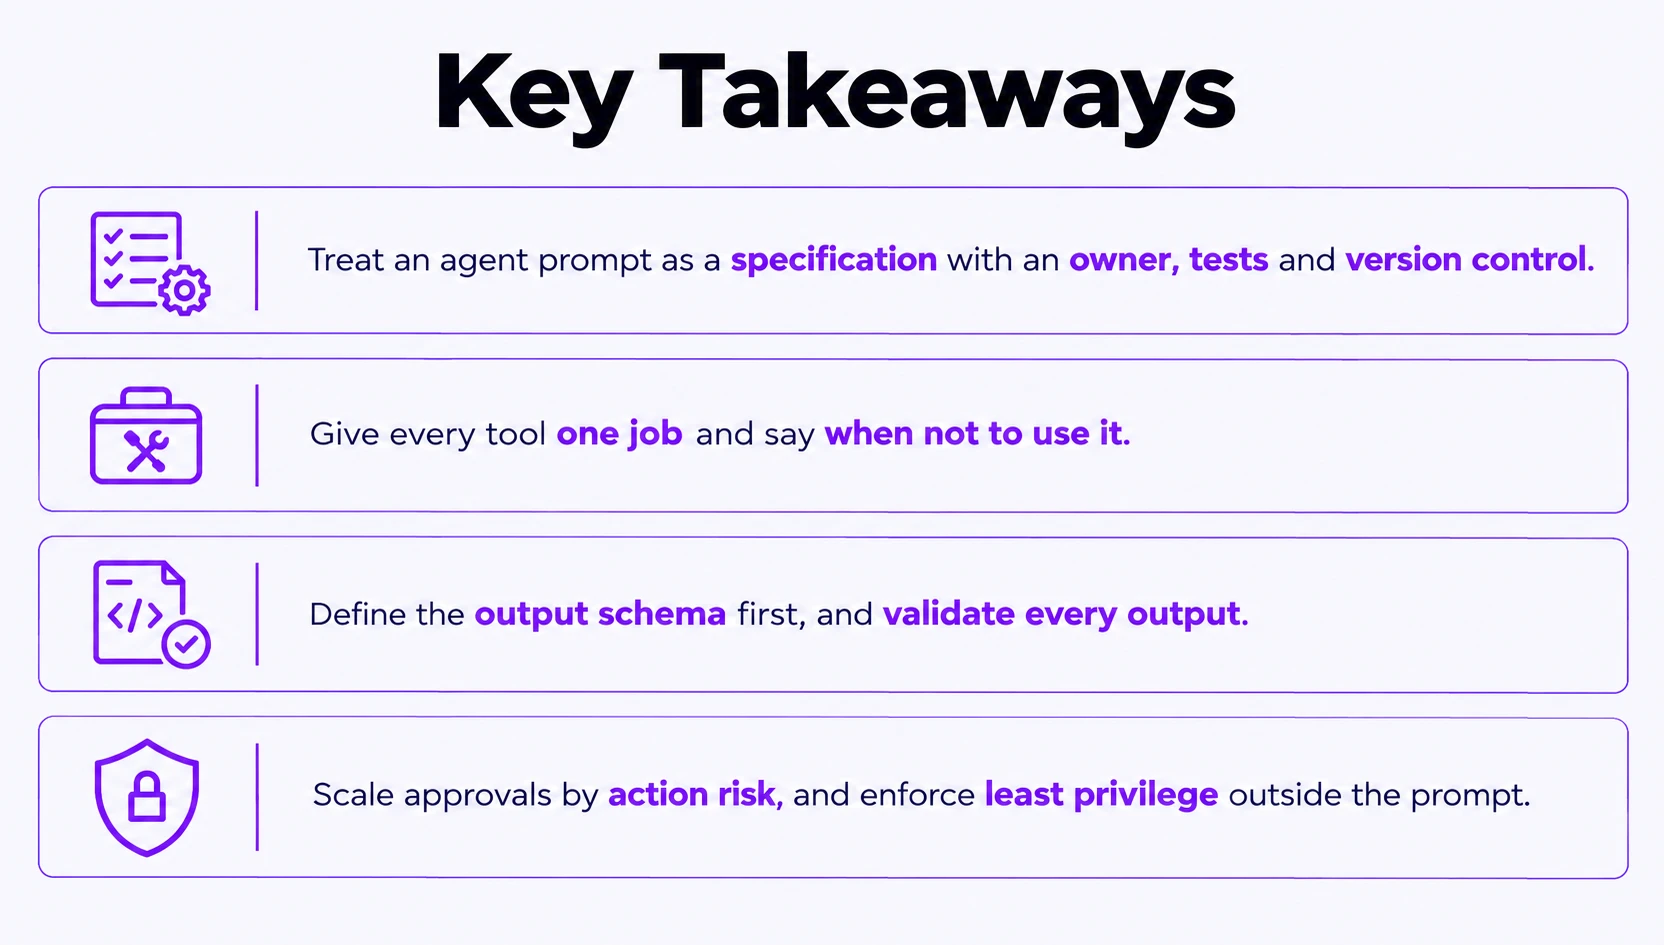
Agentic AI prompt engineering comes down to three commitments: Specify role and scope, make every tool unambiguous, and validate and permit every output before it touches a system. None of that is clever, yet the first version of nearly every agent we review skips all three, and the gap only shows up in production.
Teams that have worked with BuildNexTech across 30+ industries treat the prompt as the start of a control chain, not the whole of it. What is your next agent still allowed to do without asking?
People Also Ask
What is RPA, and how does it differ from agentic AI?
RPA is robotic process automation, software that replays fixed, rule-based clicks and data entry. Agentic AI instead reads context and chooses actions, so it handles variation scripted bots cannot.
Which tasks should AI agents handle first?
Start with repetitive, well-defined workflows where outcomes are measurable and errors are easy to detect and correct. Examples include ticket classification, document extraction, and routing requests for approval. Expand to higher-risk tasks only after validating performance in real-world conditions.
How do you measure ROI on an AI agent?
Track hours returned, tickets auto-resolved and error rates against a pre-launch baseline. Count rework and escalations too, because an agent that creates cleanup work erases the savings.
What should you look for when choosing an AI implementation consultant?
Ask for a client reference with a comparable workflow, a fixed discovery scope and named engineers. Check how they measure outcomes and whether handover documentation exists.
How should we handle sensitive customer data in agent prompts?
Pass only the fields a task needs, mask identifiers before they reach the model, and keep personal data out of logs. Confirm your model provider's retention terms in writing.